backend systems / production evidence
Correct systems. Unreliable data.
Backend engineering for concurrent pipelines, unreliable inputs, and the operational proof required to trust them.
Operational method
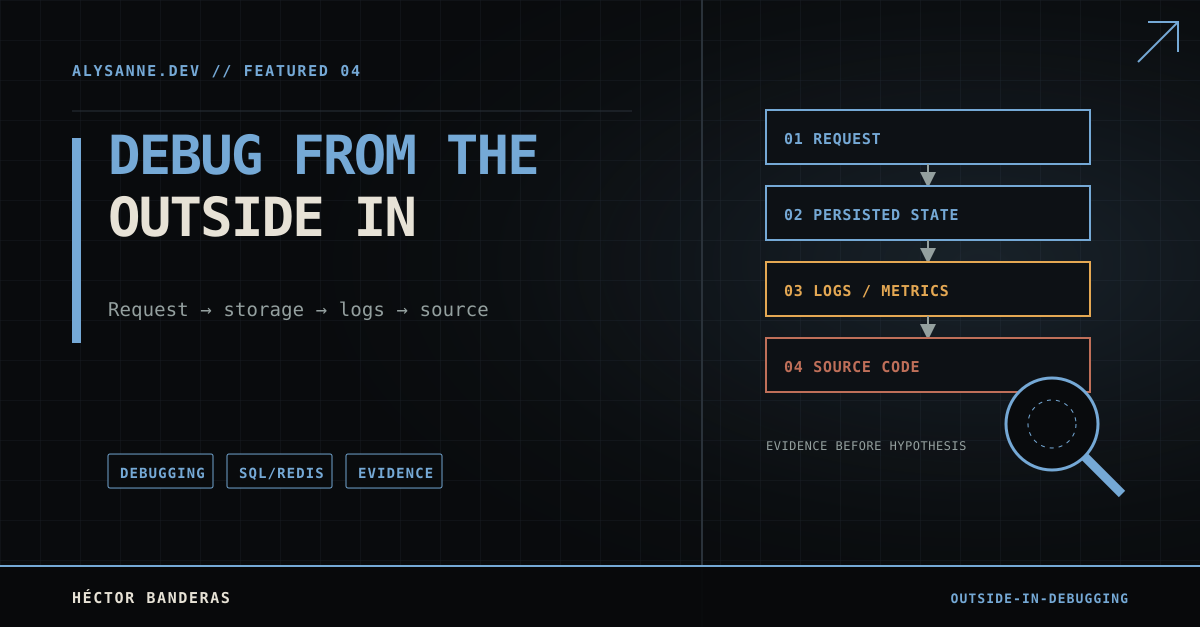
I prefer observable boundaries and concrete checks over plausible explanations.
- 01Reproduce
Begin at the system boundary with the smallest failing request.
- 02Observe
Compare logs, SQL, Redis, telemetry, and raw responses.
- 03Constrain
Revise the hypothesis until one failure mode remains.
- 04Prove
Repair the behavior, then keep it fixed with a regression test.
Recent notes
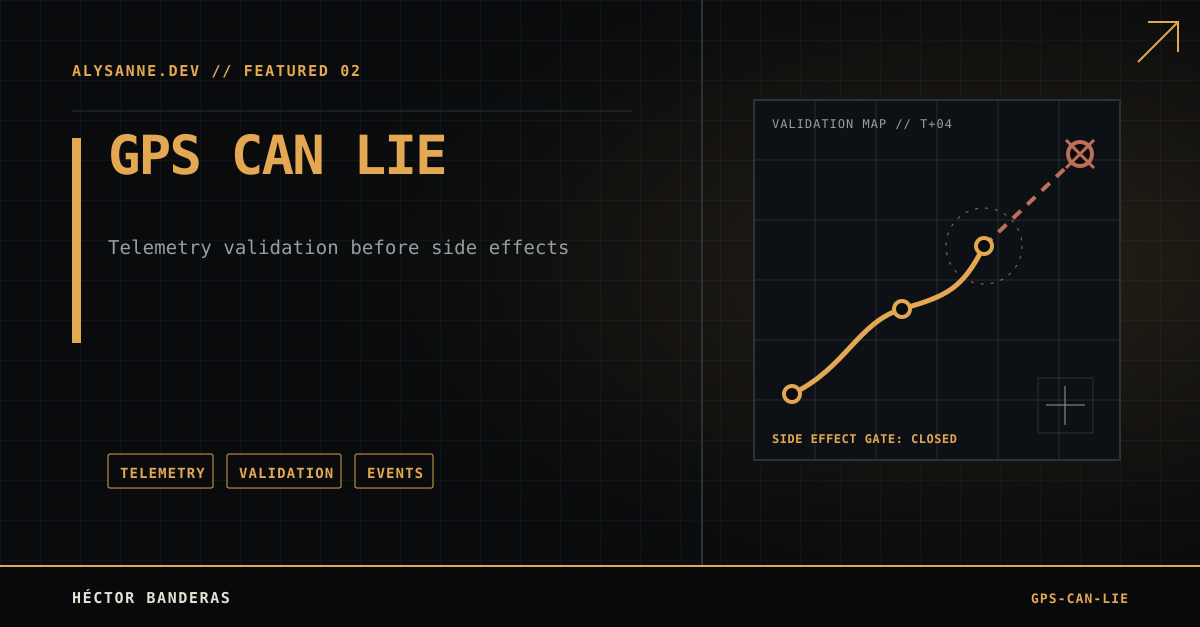
View archive- GPS can lie: designing telemetry validation before side effects
A practical ordering for duplicate, time, coordinate, rate, and movement checks in an ingestion pipeline.
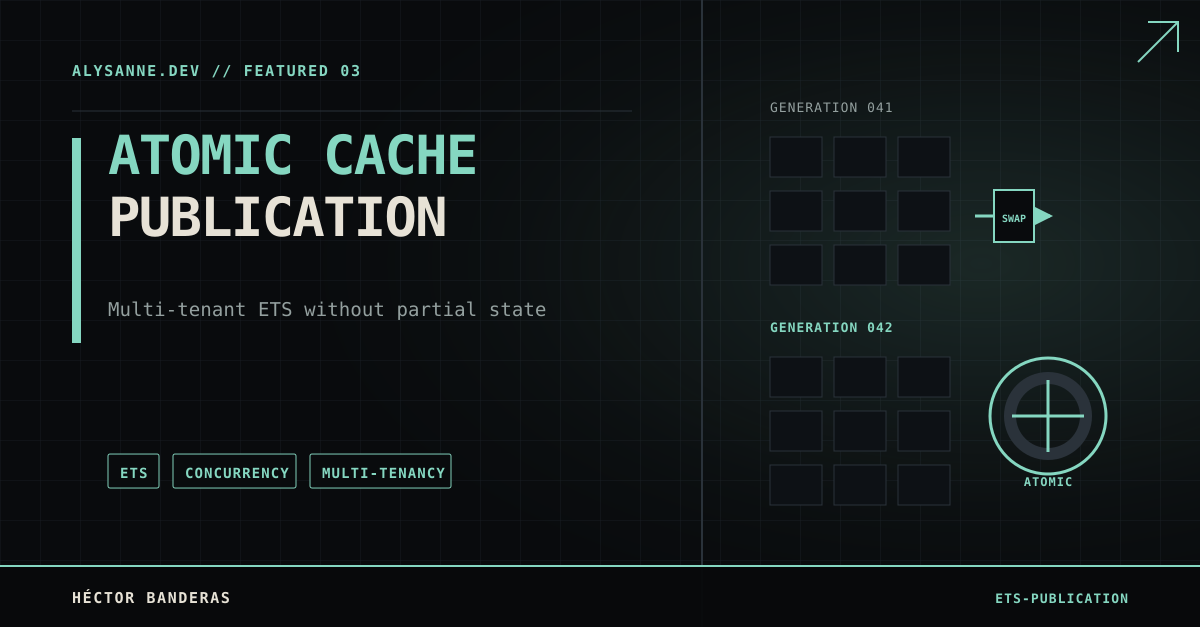
- Publishing a multi-tenant ETS index without partial state
How composite keys, one mutation owner, and generation swaps turn a fast cache into a dependable read model.
- Debugging distributed data from the outside in
Why I begin with the raw request and persisted state, then move inward toward logs and code.
Working set
- Production
- Telemetry ingestion, multi-tenant data paths, third-party APIs
- Laboratory
- Embedded Rust, local-first software, agent orchestration
- Tools
- Elixir/OTP, PostgreSQL/PostGIS, Redis/ETS, AWS, Docker, Linux